PDF Metadata Editor: The Hidden Data That Defines Your Document
View, edit, and clean the hidden "DNA" of your PDF files. Modify titles, authors, keywords, and dates to improve SEO, organization, and privacy.
What is PDF Metadata?
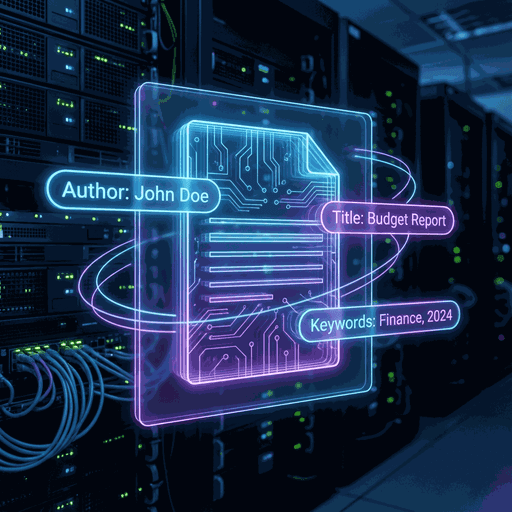
When you open a PDF file, you see text and images. But underneath that visible layout lies a hidden layer of information known as Metadata. Often referred to as "data about data," PDF metadata provides essential context to operating systems, search engines, and library software about what the file actually contains.
Standard metadata fields include:
- Title: The document's real name (often different from filename).
- Author: The person or software that created it.
- Keywords: Tags used for searching and indexing.
- Dates: Creation and modification timestamps.
While useful, this data can sometimes be incorrect, outdated, or revealing. Providing a way to edit PDF metadata is crucial for professionals who need to maintain accurate records or protect their privacy.
Why You Must Edit Metadata
SEO & Searchability
Google indexes PDF files. If your corporate whitepaper has a blank "Title" field or generic keywords, it won't rank well. Setting a descriptive Title and relevant Keywords is the #1 way to boost the visibility of your PDF assets on the web.
Privacy & Anonymization
Did you know PDFs often store the name of the computer user who created them? If you are whistleblowing, sharing legal docs, or just value privacy, scrubbing the "Author" and "Producer" fields is a critical security step.
Organization
Reference management software (like Zotero or Mendeley) relies on correct metadata. Ensuring your academic papers have the right Author/Year data ensures they are cited correctly by others.
Privacy Shield: Scrubbing identifiable information from document properties.
How It Works: Editing the Info Dictionary
PDF files contain a special object called the Info Dictionary (or sometimes XMP Metadata stream). This dictionary stores key-value pairs formatted according to Adobe's PDF specification.
Our editor works by:
- Parsing: We scan the end of the PDF file (the Trailer) to find the Info Dictionary reference.
- Extraction: We read the current values for Title, Author, Subject, Keywords, Creator, and Producer.
- Modification: When you type new values, we construct a newdictionary object or XMP packet.
- Incremental Save: We append this update to the file structure without needing to rewrite the entire PDF content, ensuring the process is lightning fast even for large files.
Frequently Asked Questions
Does changing the Title change the filename?
No. The Filename (e.g., `report.pdf`) is handled by your operating system. The Title is internal data displayed in the window bar of Acrobat or in search results. They are separate entities.
Can I edit metadata of password-protected files?
Generally, no. You will need to remove the password first (unlock the PDF) before you can modify its internal structure and metadata.
Does this affect SEO?
Yes, positively! Search engines like Google display the PDF's Metadata Title as the clickable link in search results. A clear, descriptive Title leads to much higher click-through rates.
What are XMP Metadata tags?
XMP (Extensible Metadata Platform) is a modern standard by Adobe allowing richer metadata embedding. Our tool updates both standard PDF info tags and XMP packets for maximum compatibility.
Take Control of Your Documents
Professionalize your PDFs by fixing titles, authors, and keywords. Free, instant, and secure.